a natural extension of my last post on knowledge graphs, moving from facts and entities to decisions and context.
the question isn't whether systems of record survive, they will. platforms like Salesforce, SAP, Workday, and ServiceNow already own enterprise data. the real question is where does intelligence actually live?
Today's systems capture state.
Every modern enterprise platform is, at its core, a database of outcomes:
- a deal was approved.
- a ticket was closed.
- a limit was overridden.
What they don't capture is the reasoning behind those outcomes: the exceptions, the trade-offs, the precedent that someone leaned on at 2:47pm before signing off. That layer rarely shows up in the system of record. It lives somewhere messier.
Where the missing reasoning lives.
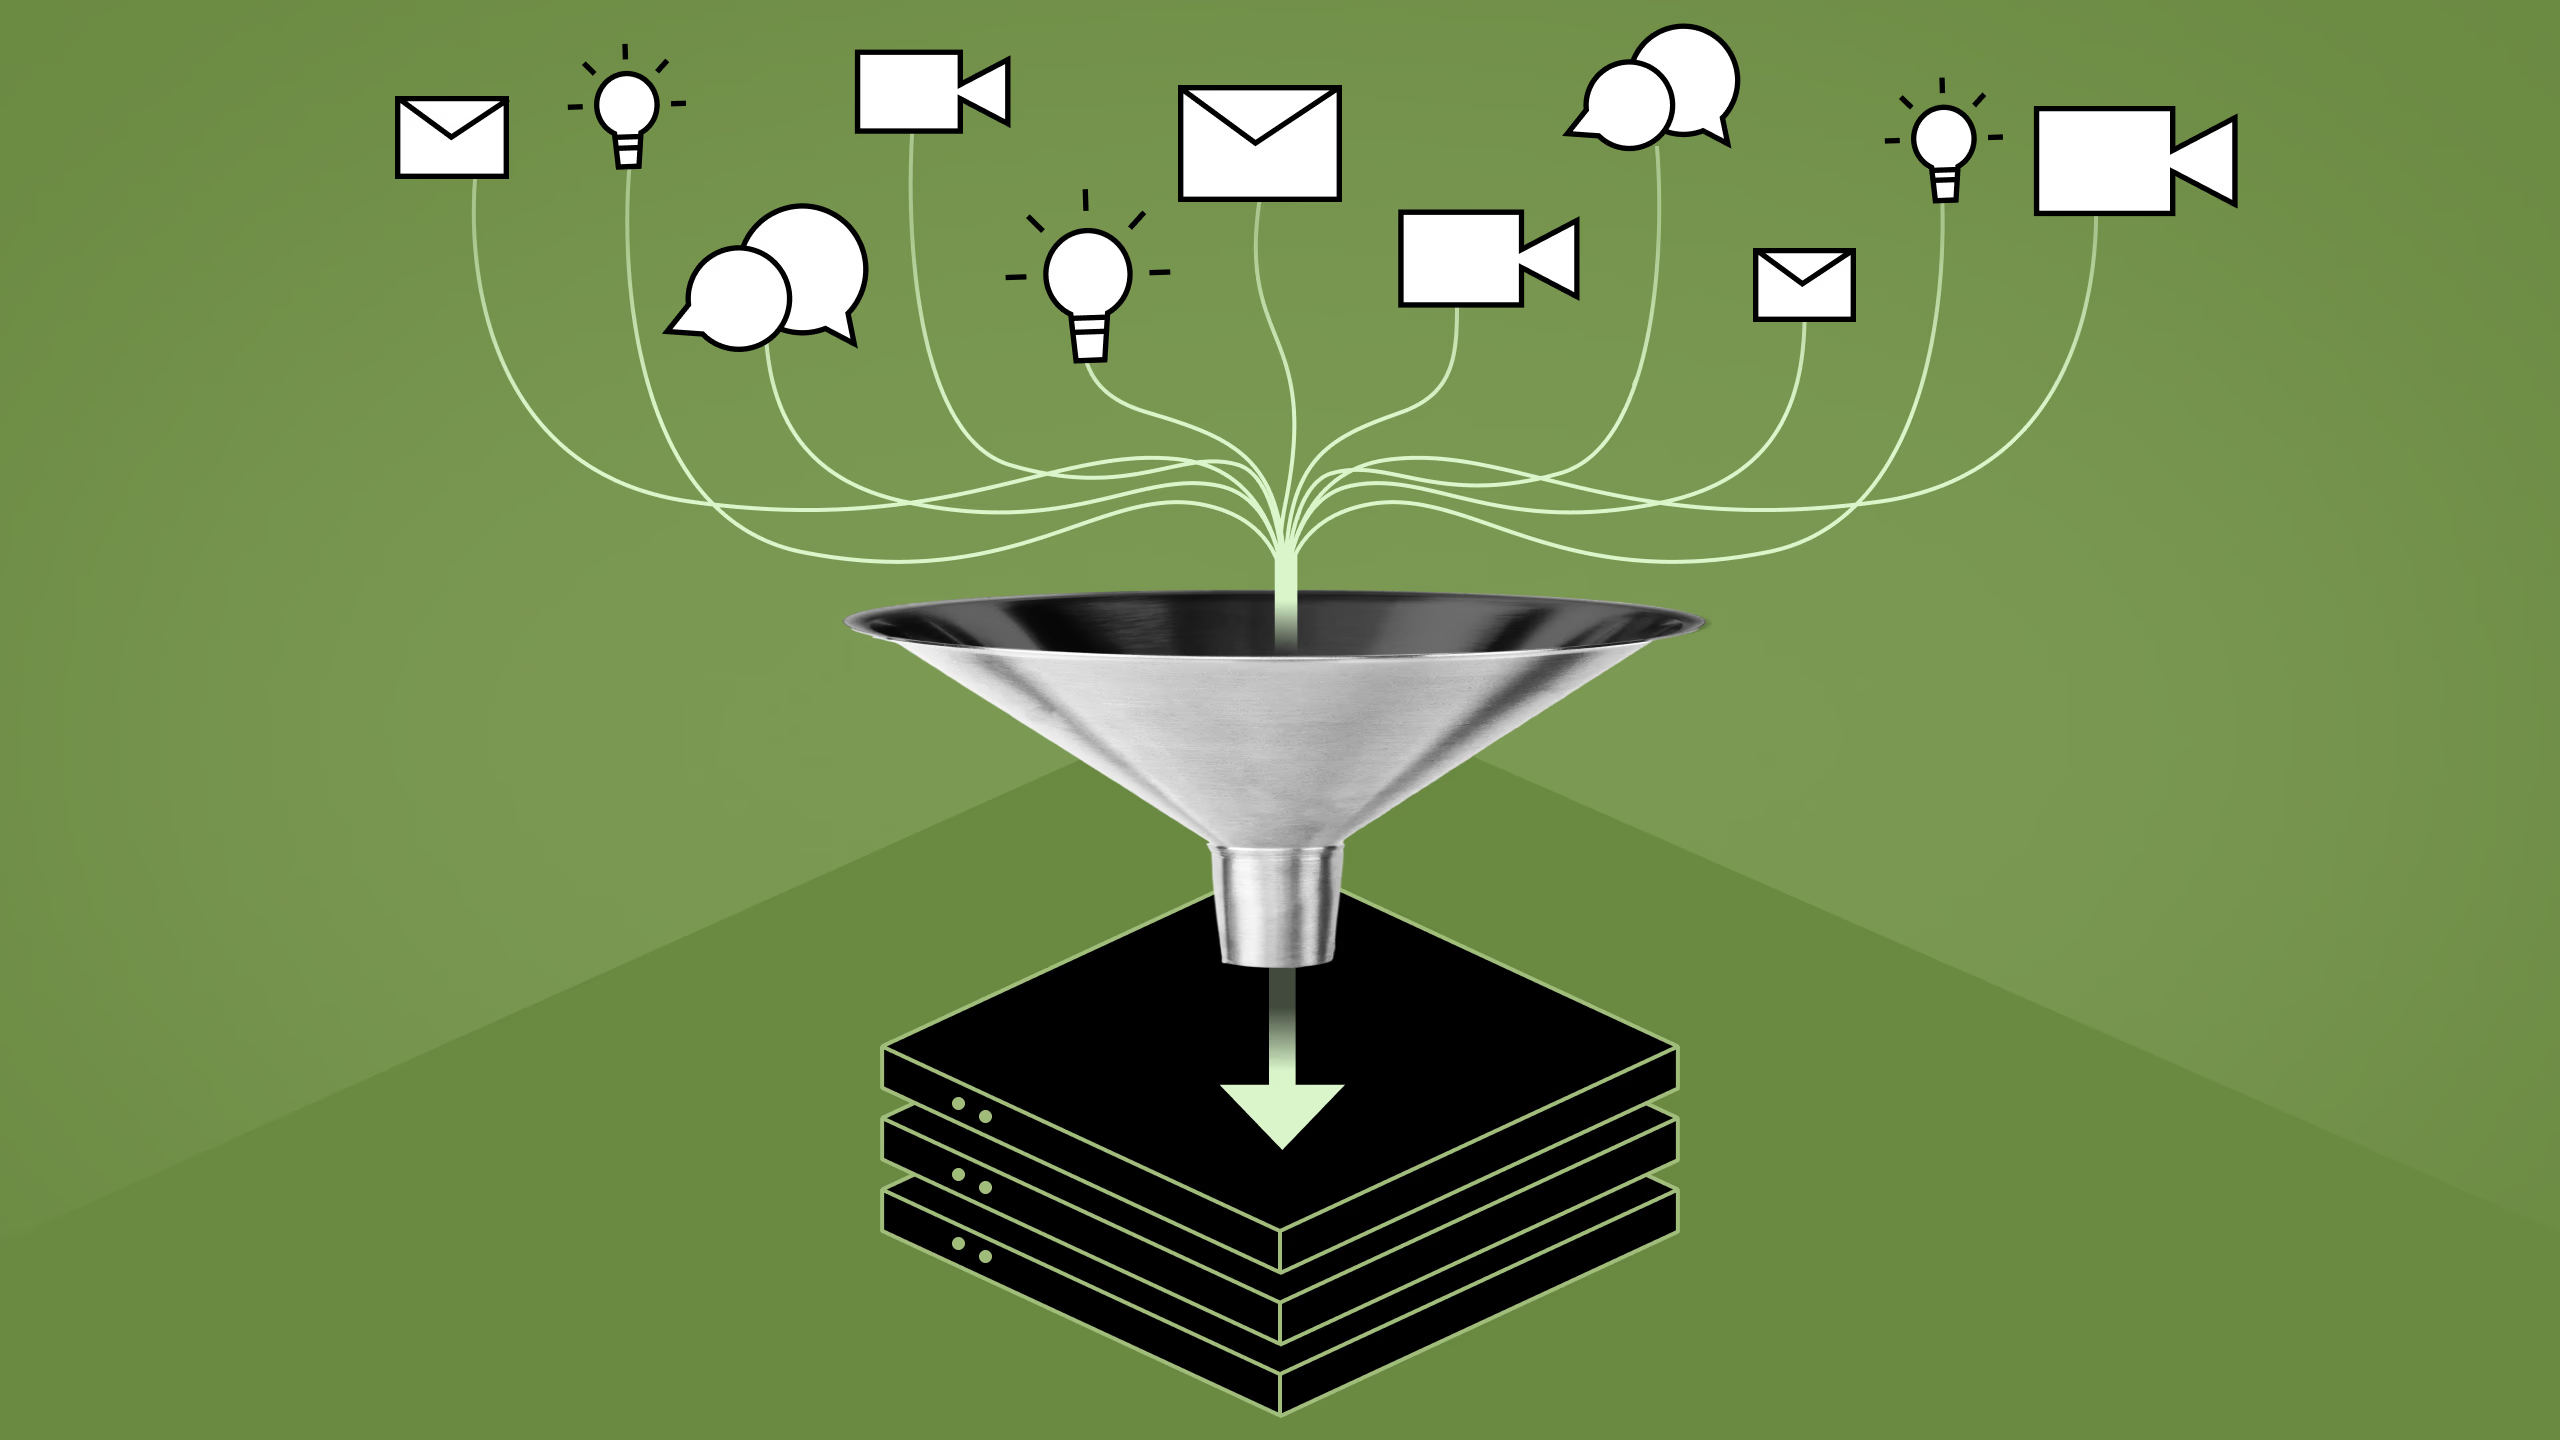
Slack threads. Email chains. Zendesk replies. Jira comments. Confluence pages. Notion docs. PagerDuty timelines. Hand-written call notes. And, most often, inside someone's head, retrievable only by asking nicely on a Tuesday.
the "why" of any enterprise decision is scattered across 6+ systems
That missing layer is exactly where AI breaks down. Give an LLM your CRM and it can tell you what happened. Ask it why the discount got approved last quarter, and the answer never lived in a queryable place.
A worked example: the discount approval.
Here's the pattern, concretely. Acme Corp asks for 30% off. The deal closes. Six months later, your AI sales-assistant tells a new rep they can offer Beta Corp the same deal because Acme got it. Beta is half the size, in a different segment, and was already willing to pay list. You just lit money on fire.
What the system of record knows:
- Acme's contract is closed-won at 70% list price.
- The discount field is set to 30%.
- Approver: VP Sales.
What the system of record doesn't know:
- Acme had a competing offer from a named competitor (mentioned in three Slack threads).
- The discount was justified because Acme committed to a public case study, referenced in an email and a marketing brief, not anywhere in the CRM.
- VP Sales explicitly noted "don't treat this as precedent" in a voice memo.
- Two weeks later, legal flagged a similar pricing scenario as risky.
A context graph would carry all of that, as edges typed justifiedBy, contradictedBy, notForPrecedent. When the AI assistant queries "is this a precedent?", it's no longer guessing. it's walking edges that say no, and here's why.
Enter the context graph.
A context graph isn't a replacement for the system of record. it's an overlay intelligence layer. Think of it as a structured memory that sits above your existing tools and stitches together:
- entities, events, policies, and people
- connected through time, causality, and precedent
- capturing decision traces, not just final outcomes
the context graph sits above existing systems. it doesn't replace them
What's actually in the graph.
Stripped to its essentials, a context graph models four kinds of nodes and the typed edges between them. The schema is small on purpose. most of the value is in the connections, not the node types.
Nodes
- Entities: accounts, deals, tickets, people, products.
- Events: approvals, edits, escalations, outages.
- Policies: pricing rules, SLAs, compliance gates.
- Reasoning artifacts: Slack threads, voice memos, email chains.
Edges
- justifiedBy: links an outcome to its rationale.
- contradictedBy: flags conflicting evidence.
- precededBy / followedBy: temporal ordering of events.
- overrides / supersededBy: exception tracking.
- notForPrecedent: explicit precedent exclusion.
The edge schema is the moat. Anyone can dump events into a database. The hard part is deciding what relationships matter and enforcing them consistently, because the quality of the graph is bounded by the precision of its edge types.
How you'd actually build one.
The architecture isn't exotic. It's three layers stacked thoughtfully.
- Ingest from everywhere. Webhooks from Slack, the CRM, Zendesk, Jira, PagerDuty, GitHub, your email server. The bias is broad and shallow: capture more than you think you need, you can always prune later.
- Extract reasoning with LLMs. Run incoming messages and documents through extraction prompts that pull out entities, events, and candidate edges. The LLM is the extractor, not the memory.
- Persist as a graph, not as text. Write extracted triplets into a graph database (Neo4j, Memgraph, Neptune). Every edge carries provenance (which message, which timestamp, which confidence score) so you can audit it later.
- Query with hybrid retrieval. Graph traversal for structural questions ("has this exception been approved before?"), vector search for the natural-language texture ("what was the tone of the customer's last email?"), and an LLM on top to compose the answer.
The thing that separates a real context graph from "just dump everything in Snowflake" is step 2 done seriously. Extraction with a typed schema, validated by rules, with explicit handling of conflicting claims, is what gives you something reasoning-grade rather than reporting-grade.
What a context graph isn't.
The category is new enough to get confused with adjacent things. It is not:
- A data warehouse. Warehouses model state at rest; context graphs model decisions and reasoning across time. Different shape, different queries.
- RAG over your wiki. RAG retrieves passages that mention keywords. A context graph traverses typed edges that encode causality. RAG can tell you what was said; the graph can tell you what it meant for.
- Agent memory. Mem0, Letta, Zep solve conversational continuity for a single agent. Context graphs solve organizational memory across humans, agents, and time.
- A knowledge graph. KGs structure timeless facts: drugs treat diseases, companies employ people. Context graphs structure time-stamped reasoning: why this person, this exception, this Tuesday.
if knowledge graphs structure what is true,
context graphs structure why something was done.
Why incumbents struggle to build this layer.
Warehouses becoming truth registries and CRMs becoming state-machines-with-APIs has made enterprise data more accessible than ever. But that solves access, not decision traces.
Salesforce is pushing Agentforce, ServiceNow has Now Assist, Workday is building HR agents. The pitch is consistent: "we have the data, now we add intelligence."
But these agents inherit two structural limits from their parents:
1. they only see current state.
Salesforce knows what an opportunity looks like now, not what it looked like when the discount was approved. When a record gets edited, the justification evaporates. No replay. No audit. No precedent.
2. they inherit blind spots.
A real support escalation doesn't live in Zendesk alone. It depends on CRM data, billing SLAs, PagerDuty outages, and the Slack thread where someone said "ship it anyway." No single system owns that.
There's a third, more subtle limit too: incentives. Salesforce's business is selling more Salesforce. A context graph that lets a customer see their data is irrelevant whether it lives in Salesforce or somewhere else, is the kind of thing only a startup or a neutral platform can ship without internal antibodies forming.
The hard parts (and they are hard).
A context graph is a beautiful idea on a whiteboard. In production, four problems eat most of the engineering budget.
- Identity resolution across systems. Slack'sU02ABCDE, Salesforce's003xx00000, and an email address all sometimes refer to the same human. Stitching these into a single entity reliably is a classic, unglamorous problem.
- Conflicting claims. Slack says one thing, the CRM says another, and the call notes contradict both. The graph has to express disagreement without collapsing it, every edge carrying provenance and confidence.
- Schema drift. The org reorganizes. New deal stages appear. A new tool gets adopted. Your edge types from six months ago don't cover it. Migration is real work that ships zero new features.
- Privacy and access control. Decision context often includes sensitive material: performance reviews, legal advice, board discussions. Edge-level permissions are non-trivial, and getting them wrong is the kind of bug that ends a company.
Builder takeaways.
- 01don't replace systems of record; sit above them.
- 02treat decision context as a first-class graph, not unstructured text.
- 03use LLMs to extract reasoning, but persist memory in structure.
- 04the moat is cross-system decision history, not the LLM, not the UI.
- 05provenance is non-negotiable. every edge needs a source, a timestamp, and a confidence score. without that, the graph is just another black box.
- 06start with one decision type (pricing approvals, support escalations, hiring committees) and prove value narrowly before expanding the schema.
CRMs standardized customer data. Context graphs may standardize enterprise decision-making, capturing not just the answer, but the trail of reasoning that produced it.
feels early. but foundational.